The NIST glossary defines indirect prompt injection as an attack executed through control of a resource rather than the user's direct input. For the broader definition, see what prompt injection is; for recognition patterns, see prompt injection examples.
Direct vs indirect prompt injection
Both are forms of prompt injection. The distinction is where the conflicting instruction originates and which trust boundary is crossed. Terminology varies across vendors and research papers, but the practical difference is consistent.
| Dimension | Direct | Indirect |
|---|---|---|
| Immediate source | Active user input | External or retrieved content |
| Trust-boundary issue | User input attempts to override a higher-trust application instruction | Untrusted content is treated as if it can instruct the system |
| Typical route | Chat or form input | Retrieval, browsing, email, document parsing or ingestion |
| Example | An application requires a fixed summary format; a user tries to override that rule with an unrelated response | A report received from an external source contains a visible sentence asking the AI to omit a section when summarising |
| Relevant controls | Instruction handling and output constraints | Source treatment, pre-ingestion checks, context isolation, least privilege and action approval |
The NIST AI 100-2 taxonomy and OWASP guidance both treat these as related patterns within the broader prompt-injection category. The Greshake et al. paper demonstrated the indirect class through remotely supplied content, establishing that the attack surface extends beyond the user's own input.
How indirect prompt injection travels through a document workflow
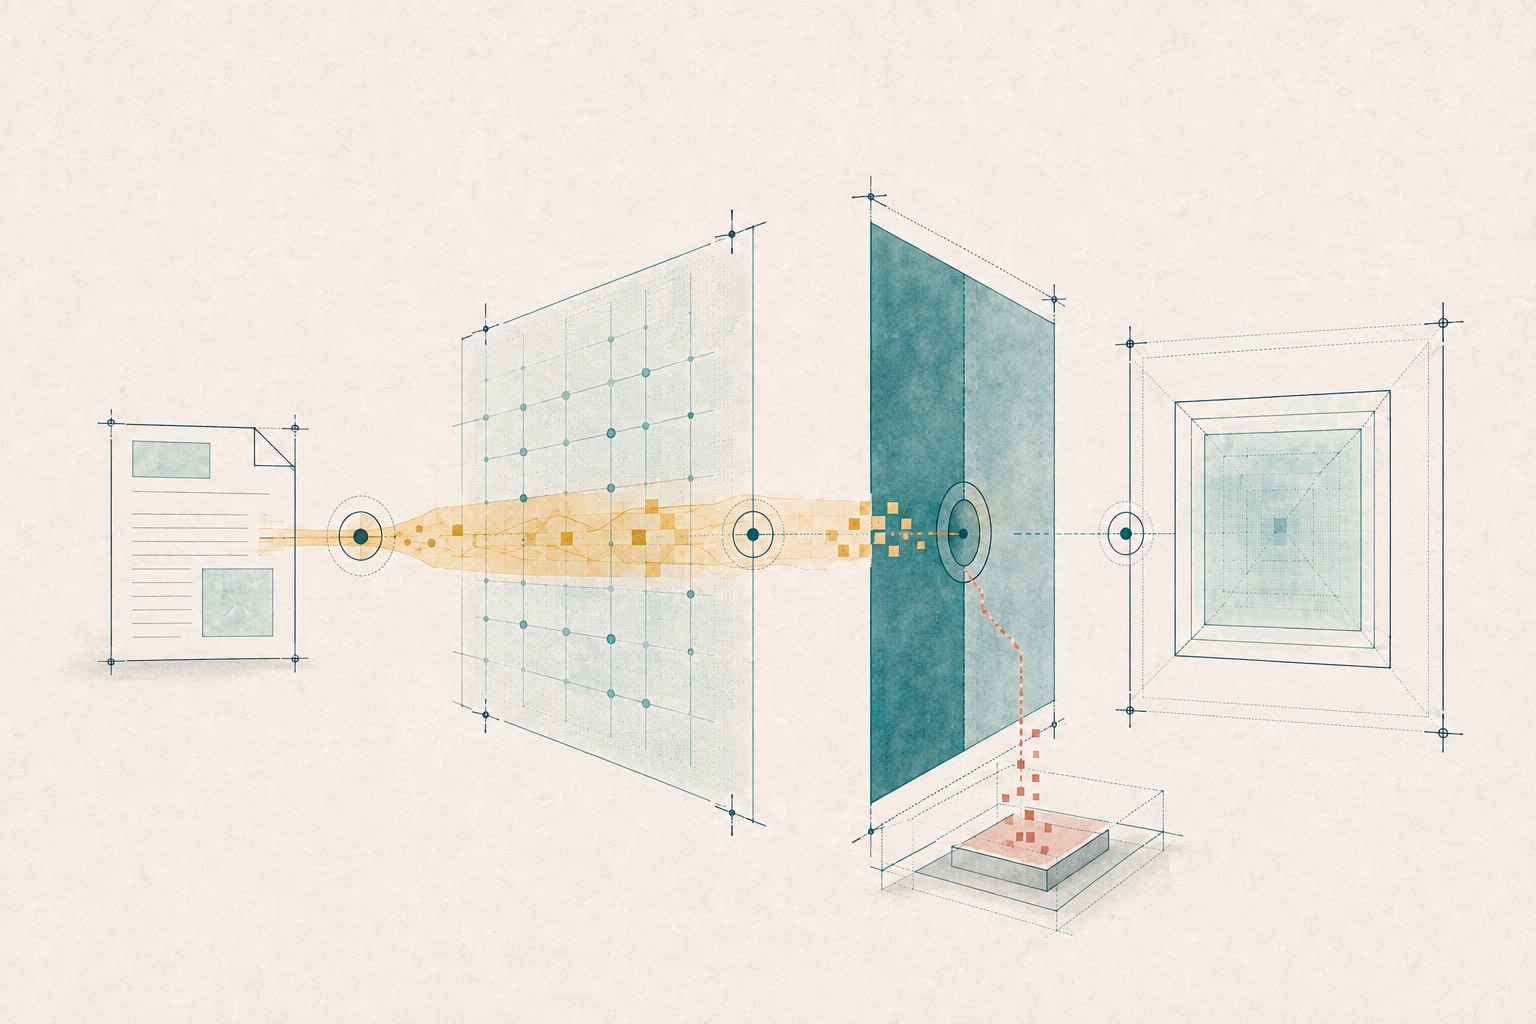
The following five stages trace the path from an external document to a possible model response or action. Each stage introduces a variable that affects whether and how the content influences the system.
1. An external source supplies the document
The source may be a known contact, an unknown sender or a compromised account. Provenance affects how carefully the document should be handled, but it does not determine the document's content. A file from a known contact can still contain instruction-like text if the account was compromised or the file was forwarded from elsewhere. Conversely, a file from an unfamiliar source may be entirely benign. The Microsoft Security Response Center describes this as the starting point of the source-to-action chain.
2. A parser or retrieval step exposes content
An application may extract visible text, machine-readable structures, metadata or other supported content from the document. What reaches the model can differ by parser and format. A PDF, for instance, can contain extractable text or objects that are not apparent in the ordinary rendered view, as documented by the PDF Mirage study and the CrackedPDFs benchmark. For format-specific detail, see visible and machine-readable content in PDFs.
Hidden content is not required. Ordinary visible text may carry an instruction, as the OWASP guidance and OpenAI's explanation both make clear. The risk lies in the path from untrusted content to a consequential output, not in concealment alone.
3. The application places content beside instructions
This is the architectural tension at the heart of prompt injection. Trusted task instructions and untrusted source material can share the same model context without a hard security boundary separating them. The NIST AI 100-2 taxonomy frames this as the concatenation of untrusted input with a prompt created by a higher-trust party. The resulting context does not provide an enforceable boundary between the task and material about the task.
4. The model may be influenced
Possible content-level effects include task substitution, omission of relevant information and distortion of the response. In its benchmarked settings, the BIPIA benchmark identified two recurring difficulties among the tested models: distinguishing informational context from actionable instructions, and recognising that instructions inside external content should not control the task. Behaviour can vary as models and mitigations change.
Influence is conditional. The signal must survive extraction, enter the model context, compete with the application's instructions and affect the output. Failure at any point breaks the chain. Observing the text establishes its presence; showing effect requires a defined comparison.
5. Permissions determine the possible impact
The final boundary is capability. Without protected data or connected tools, the possible consequence is limited mainly to the response. Once the application can retrieve, send or modify information, those permissions determine what an influenced output could become. OpenAI's agent-design guidance therefore places controls at that data-and-action boundary.
A changed output or proposed action is evidence of influence, not by itself evidence of harm. Harm is a further claim that requires evidence of an adverse consequence in the surrounding workflow. Attempt, influence and harm must remain distinct throughout any assessment.
Why this is not the same problem as SQL injection
A common mental model treats prompt injection as analogous to SQL injection: untrusted input is injected into a system that was not designed to interpret it as code. The UK NCSC explains why this analogy is incomplete.
In a well-designed database application, a query layer can separate code from parameters with deterministic rules. A parameterised query treats user input as data, not as executable code. Natural language does not offer an equivalent separation boundary. Task instructions and the information needed to perform the task often arrive together in the same context, and the model must interpret both as language.
Quoting, delimiters or keyword blocks can help in some configurations, but they do not create an absolute data/instruction boundary. Paraphrasing and benign instruction-like prose make simple keyword matching especially weak. The OWASP guidance and NIST AI 100-2 both acknowledge that some controls reduce risk without eliminating it. Mitigation is still possible, but the deterministic guarantees available in structured query languages do not transfer directly to natural-language model inputs.
What can an indirect injection affect?
The consequences of an indirect injection depend on the workflow context. The following categories move from content-level effects to wider consequence boundaries.
Response quality and task integrity
A summary may omit a caveat, favour a particular claim or address the wrong task entirely. The OWASP guidance lists output manipulation as a possible effect. Unexpected output is not automatically evidence of injection: model error, ambiguous user instructions and ordinary hallucination can produce similar symptoms. Security relevance is clearest when an untrusted party can intentionally influence the content and the model's deviation crosses an intended trust boundary.
Confidentiality
A disclosure attempt becomes an actual disclosure only if the application exposes additional protected context and the model or system releases it. The attempt remains a review signal even when no protected data is available or released. A document that is summarised in isolation, with no access to unrelated data, has a narrower confidentiality boundary than the same document processed by a system that can reach private files, credentials or other users' data. Never assume that reading a PDF alone gives it access to unrelated information.
Connected actions
Tool-enabled systems can create a larger consequence boundary. An agent that can send messages, modify files or query external services has a wider range of possible actions than a text-only summariser. Unintended actions depend on permissions and application safeguards, not merely the document text. The Microsoft Security Response Center and Google's layered-defence guidance both emphasise that the action boundary, not the content alone, determines the worst-case impact.
Can indirect prompt injection be detected?
Filters, classifiers and document analysis can identify supported signals and reduce risk. No benchmark result establishes a universal clearance verdict across formats, parsers, models and real-world distributions. This limitation is consistent with the detection and filtering limits described by NIST AI 100-2 and the NCSC.
Keyword matching alone misses paraphrases and can flag legitimate instructions or quoted research. A security paper that quotes attack patterns, a form template with imperative language, or a project brief with formatting rules can all resemble suspicious patterns to a pattern-matching check. OWASP describes common variation and obfuscation patterns; in practice, deterministic matching should therefore be treated as a reproducible triage signal rather than proof.
A useful result reports evidence, location, coverage, limits and the next action rather than only a binary verdict. For the actual intake procedure, see check a document for prompt-injection signals. For focused evidence on specific document types, see hidden prompts in research papers and CV and resume prompt injection.
Layered controls for external documents
The three layers below bring together practical recommendations from OWASP, the UK NCSC, Microsoft, Google and OpenAI. They are a practical framework rather than a mandated standard.
Before ingestion
- Verify provenance and necessity: where the document came from, who produced it, and whether it is needed for the task.
- Scan supported surfaces and record incomplete coverage.
- Hold ambiguous cases for human review rather than proceeding on the assumption that an unflagged document is clear.
During processing
- Mark external content as untrusted within the application design.
- Minimise sensitive context and restrict tools and permissions to what the specific task requires.
- Use source-to-action constraints rather than relying only on content classification.
Before output becomes action
- Validate proposed actions and destinations against the user's original task.
- Require explicit user approval for consequential operations such as sending a message, modifying a file or accessing a new data source.
- Monitor and retain enough provenance for investigation.
These layers reduce risk. They do not guarantee that an injection cannot succeed, and no single layer, including a guardrail model, is a complete assurance.
.mdSiren's role before ingestion
.mdSiren · Available now
.mdSiren is a document security checkpoint for AI systems. Standard Scan puts a checkpoint before extracted content reaches AI context by checking the exact document version for supported prompt-injection and document-borne risks.
The version is routed to Approved, Needs review or Quarantine. The private Library makes only current eligible Approved versions available with their scan records, ready for retrieval into your AI workflow. Every result remains limited to the checks and coverage reported for that version.
See how it works · Checks and coverage · Coming soon
Frequently asked questions
What is the difference between prompt injection and indirect prompt injection?
Indirect injection is a subtype in which the instruction-like content arrives through an external source rather than the active user's direct input. The NIST glossary defines it as an attack executed through control of a resource. A document supplied by a third party is a typical indirect route.
Can indirect prompt injection come from a PDF?
Yes, if relevant visible or machine-readable content is extracted and supplied to the model. The effect depends on the whole workflow: the parser, the model's context, and the downstream permissions. See visible and machine-readable content in PDFs for format-specific detail.
Is indirect prompt injection malware?
No. It targets an AI system's handling of content. A malicious campaign could combine prompt injection with other techniques, but the two are distinct security categories. .mdSiren does not provide a comprehensive malware verdict.
Can a filter stop every indirect prompt injection?
No universal filter has been established across systems and distributions. Layered controls can reduce risk, but no single control prevents every attack. The NCSC and OWASP both make this limitation explicit.